Replicating PostgreSQL Without Touching Production: Why We Chose Bucardo Over AWS DMS
When you're working with production databases, there's one rule you rarely get to break: don't touch what's working. And yet, sooner or later, you'll need to move data around — migrating to new infrastructure, syncing environments, feeding an analytics pipeline — without being able to afford a single second of downtime.
That was exactly the scenario we faced in a recent project. The "obvious" choice was AWS Database Migration Service (DMS), Amazon's managed tool for this kind of job. But once we looked closer at the requirements, we ran into a blocker that matters a lot more in production than it might seem at first glance.
The Problem with AWS DMS: Restarting the Database Isn't Always an Option
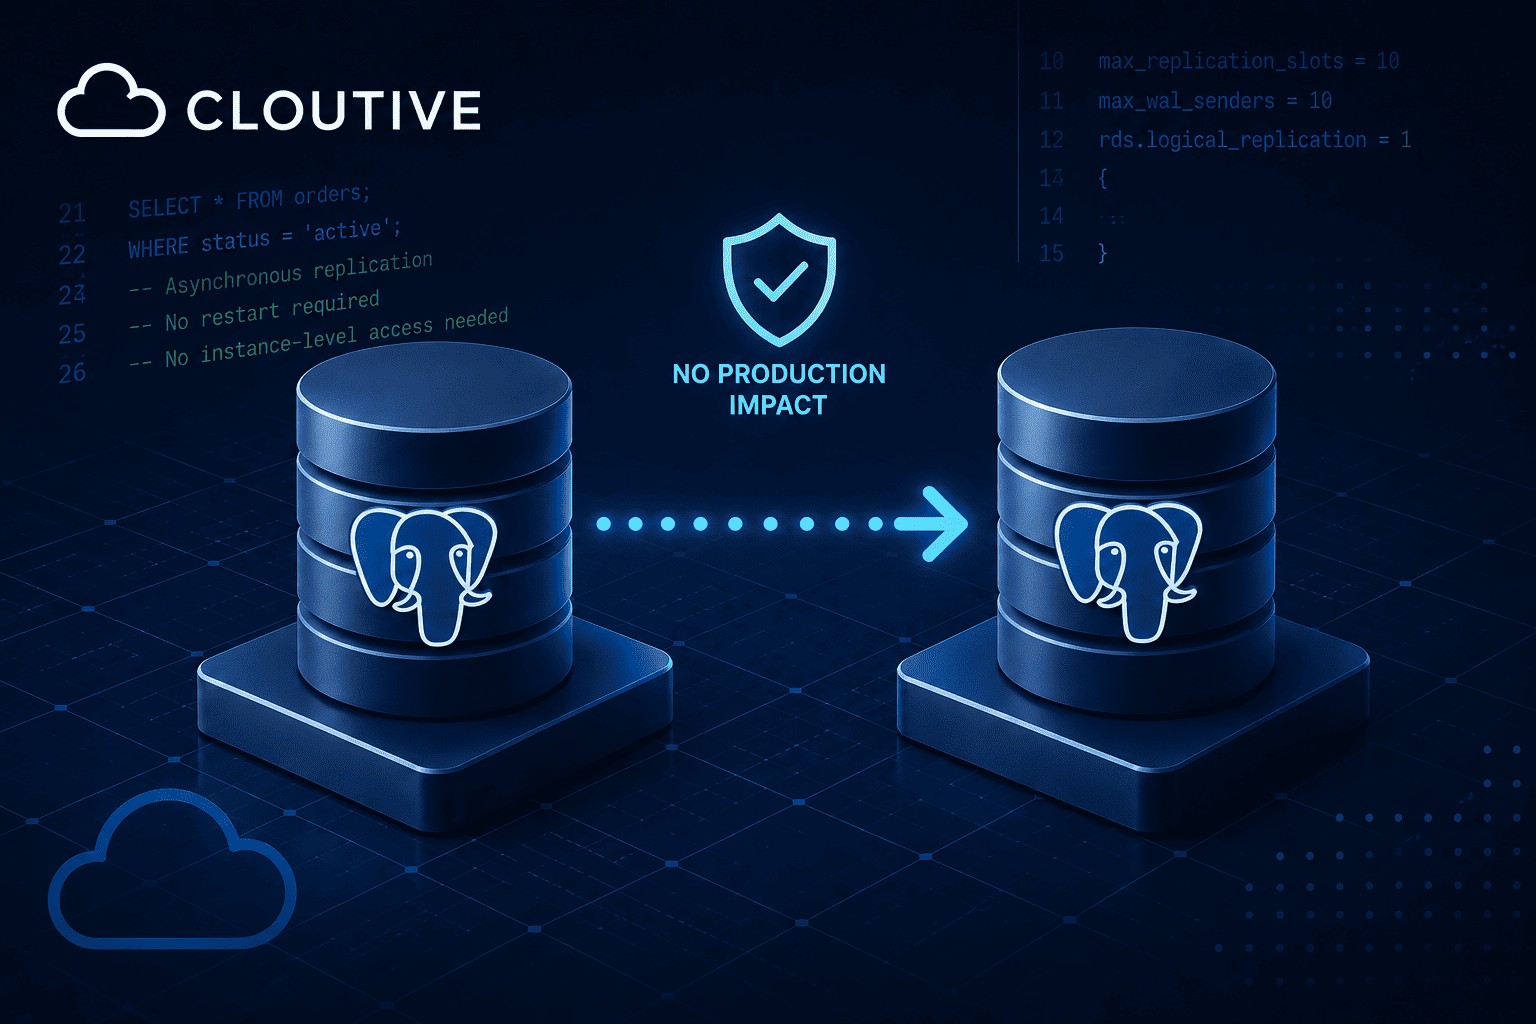
For AWS DMS to perform logical replication, PostgreSQL needs several parameters configured beforehand: wal_level, max_replication_slots, max_wal_senders, rds.logical_replication, among others. The inconvenient part is that these parameters can't be changed on the fly — they require an instance restart.
In an environment with strict uptime requirements, that alone rules the option out. On top of that, there's another common wrinkle with managed services: you often don't have root access to tweak instance-level settings, which narrows your options even further.
We needed something that could operate outside those constraints. That's where Bucardo comes in.
What Is Bucardo, and Why It Fits This Kind of Scenario
Bucardo is an open-source asynchronous replication system for PostgreSQL, written in Perl. Unlike native logical replication or services like DMS, Bucardo operates at the application level, using triggers to detect and propagate data changes between databases. That makes it especially useful when:
- You can't restart the source database.
- You don't have instance-level access to modify replication parameters.
- You need something more flexible than simple master-slave replication, such as multi-master setups with custom conflict resolution.
- You want the whole process to be self-managed, with local logs and full control over the infrastructure.
In short: where DMS demands structural changes, Bucardo adapts to the environment as-is.
Getting Hands-On: Installation and Setup on Ubuntu 24.04
Below is the step-by-step process we followed to get Bucardo up and running with an active sync between a source and a destination database. The reference environment is Ubuntu 24.04 (64-bit, x86).
1. Install PostgreSQL and Dependencies
apt-get update
apt-get install -y postgresql
apt-get install -y libdbix-safe-perl libdbd-pg-perl libboolean-perl postgresql-plperl
mkdir -p /var/log/bucardo /var/run/bucardo
chown -R postgres:postgres /var/log/bucardo /var/run/bucardo
apt-get install -y bucardo
It's normal to see this error at this stage — it resolves itself in a later step:
psql: error: connection to server on socket "/var/run/postgresql/.s.PGSQL.5432" failed: FATAL: role "bucardo" does not exist
2. Configure .bucardorc
bash
vi $HOME/.bucardorc
File contents:
dbhost=127.0.0.1
dbname=bucardo
dbport=5432
dbuser=bucardo
3. Create the Bucardo User and Database
bash
sudo su - postgres -c "psql postgres"
Inside the psql prompt:
sql
CREATE USER bucardo WITH LOGIN SUPERUSER ENCRYPTED PASSWORD 'bucardopass';
CREATE DATABASE bucardo;
CREATE EXTENSION plperl;
4. Add Credentials to .pgpass
bash
echo "127.0.0.1:5432:bucardo:bucardo:bucardopass" > $HOME/.pgpass
chmod 0600 $HOME/.pgpass
5. Prepare the Destination Database
If the source database is large, it's best to dump only the schema:
bash
pg_dump "host=source_host port=5432 dbname=source_db_name user=source_db_user" --schema-only | grep -v 'CREATE TRIGGER' | grep -v '^--' | grep -v '^$' | grep -v '^SET' | grep -v 'OWNER TO' > source_schema.sql
And restore it on the destination:
bash
psql "host=destination_host port=5432 dbname=destination_db_name user=destination_db_user" -f source_schema.sql
Then add credentials for both source and destination:
bash
cat >> $HOME/.pgpass <<EOL
destination_host:5432:database_name:db_user:db_pass
source_host:5432:database_name:db_user:db_pass
EOL
6. Install Bucardo Internally
bash
bucardo install --quiet
You can ignore this error if it shows up:
Can't open quiet: No such file or directory
7. Register the Databases
bash
bucardo add db friendly_source_db_name dbhost=source_host_name dbport=5432 dbname=db_name dbuser=db_user dbpass=db_pass
bucardo add db friendly_target_db_name dbhost=target_host_name dbport=5432 dbname=db_name dbuser=db_user dbpass=db_pass
Confirm they were registered:
bash
bucardo list dbs
8. Define the Herd (the Group of Tables to Replicate)
bash
bucardo add all tables --herd=herd1 db=friendly_source_db_name
bucardo add all sequences --herd=herd1 db=friendly_source_db_name
bash
bucardo list herds
9. Configure Sync Options
Enable more detailed logging:
bash
bucardo set quick_delta_check=0
bucardo set log_level=VERBOSE
Option A — Small databases: use onetimecopy so Bucardo handles the initial copy automatically.
bash
bucardo add sync friendly_sync_name herd=herd1 dbs=friendly_source_db_name:source,friendly_target_db_name:target onetimecopy=1
Option B — Large databases: skip onetimecopy and handle the backup/restore manually.
bash
bucardo add sync friendly_sync_name herd=herd1 dbs=friendly_source_db_name:source,friendly_target_db_name:target
After creating the sync (and before starting Bucardo), do a full backup of the source and restore it to the destination. The destination database — which up to this point only had the schema restored — can safely be dropped and recreated from the full backup.
One important detail: this backup/restore must happen after the bucardo add sync command when onetimecopy isn't used. Once the database is restored, drop the Bucardo schema that came along with the backup:
sql
drop schema bucardo cascade;
10. Start the Sync
bash
bucardo list sync
bucardo start
11. Monitoring and Maintenance
bash
tail -f /var/log/bucardo/log.bucardo
bucardo status
bucardo deactivate sync1
bucardo stop
The Result
With these steps in place, you're left with a working asynchronous replication system that runs outside PostgreSQL's core, requires no restarts, and doesn't depend on instance-level permissions. Whether for high availability, real-time analytics, or cross-region syncing, Bucardo shows that sometimes the more "hands-on" open-source tool ends up being the more practical choice over a managed service that demands conditions your production environment simply can't afford to meet.