Automating Quarterly Reporting with AWS Bedrock Agents
How we replaced a week of manual work with a one-hour autonomous pipeline without sacrificing data accuracy.
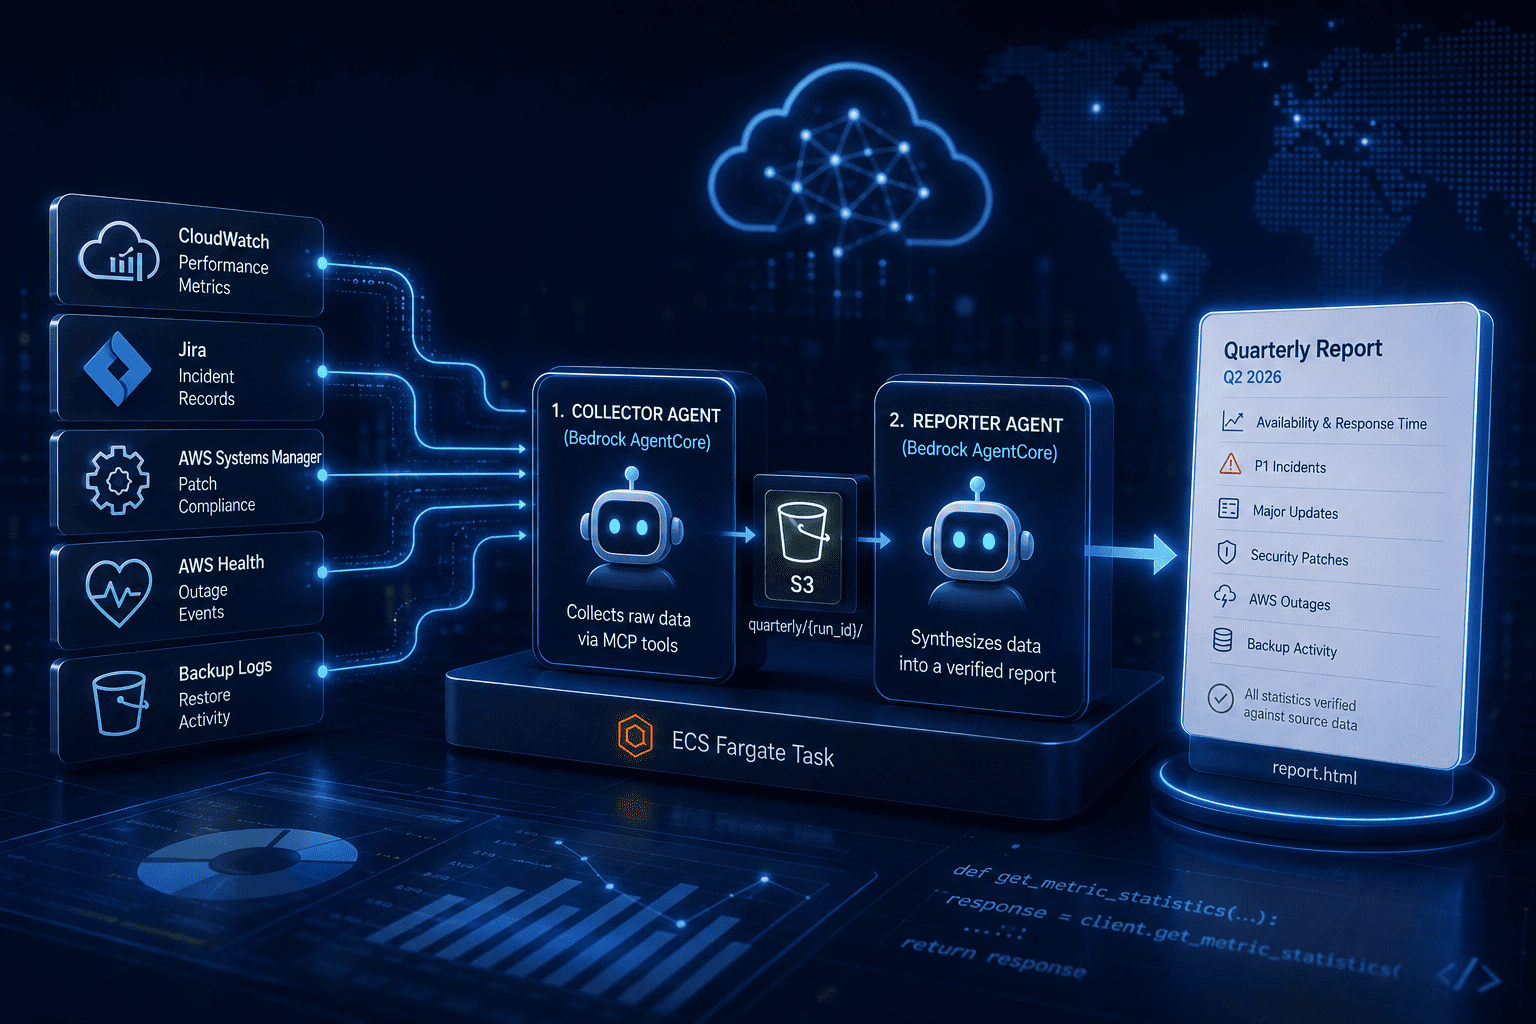
Quarterly reporting was consuming significant operational resources. Each quarter required collecting data from multiple systems: CloudWatch for performance metrics, Jira for incident records, AWS Systems Manager for patch compliance, AWS Health for outage events, and backup logs for restore activity. The manual process was time-intensive and introduced operational risk — a full week of work, data delays, and quality issues that required extensive review before stakeholders could rely on the report.
We implemented an automated solution using AWS Bedrock agents. Two agents handle the process autonomously: one to collect raw data, one to synthesize it into a report. They communicate through S3. The complete process now executes in approximately one hour, compared to the prior week-long manual process. Every statistic is verified against actual data, and the system includes structural safeguards to prevent hallucination.
The reduction in compilation time freed the team to focus on data interpretation rather than assembly.
The Architecture
An ECS Fargate task orchestrates the whole run. It invokes the two Bedrock AgentCore runtimes in sequence and writes the final report to S3.
ECS Fargate Task
  |
  |-- 1. Invoke Collector Agent Runtime (Bedrock AgentCore)
  |           |
  |           | calls tools via MCP Gateway (SigV4)
  |           |-- CloudWatch Lambda  --> S3: quarterly/{run_id}/cloudwatch/
  |           |-- Patches Lambda     --> S3: quarterly/{run_id}/patches/
  |           |-- Backup Lambda      --> S3: quarterly/{run_id}/backups/
  |           |-- Outages Lambda     --> S3: quarterly/{run_id}/outages/
  |           |-- Jira P1 Lambda     --> S3: quarterly/{run_id}/jira/
  |
  |-- 2. Invoke Reporter Agent Runtime (Bedrock AgentCore)
              |
              | reads all data from S3
              --> HTML report --> S3: quarterly/{run_id}/invoke/report.html
Both agent runtimes are invoked directly via bedrock-agentcore:InvokeAgentRuntime. The MCP gateway sits in front of the Lambda tools and authenticates all calls with SigV4.
The Collector Agent
The Collector Agent runtime receives a payload with a date range and a run_id. It calls data collection tools via the MCP gateway — each tool is a Python Lambda that queries a specific data source:
python
# cloudwatch.py - one of the per-account Lambda tools invoked by Step Functions
response = client.get_metric_statistics(
    Namespace=namespace,
    MetricName=metric_name,
    StartTime=start_date,
    EndTime=end_date,
    Period=43200,  # 12h aggregation
    Statistics=["Average"],
    Dimensions=[{"Name": "EndPoint", "Value": "app"}]
)
Each tool writes its result to quarterly/{run_id}/{tool_name}/{account_id}.json. The structure is consistent across all tools: account ID, status, the data, and a generated_at timestamp.
One strict rule: the Collector never modifies the dates it receives. Whatever start_date and end_date Step Functions pass in, those go verbatim to every tool call.
The Reporter Agent
Once collection is complete, the Fargate task invokes the Reporter Agent runtime with the same run_id. It reads a manifest of what's available in S3, then pulls each folder key by key:
quarterly/{run_id}/cloudwatch/→ response time and availabilityquarterly/{run_id}/jira/→ tickets (filtered by priority)quarterly/{run_id}/patches/→ security patchesquarterly/{run_id}/outages/→ AWS outagesquarterly/{run_id}/backups/→ backup and restore activity
The Jira filtering is strict: P1 tickets require priority == "Highest" (normalized, case-insensitive). Major updates are High or Medium. A ticket in P1 never appears in Major updates.
The Reporter only uses data it actually reads from S3. If a folder is missing, that section is marked as unavailable — it never invents numbers.
The Agent Runtime
Both agents use the Strands framework and connect to their tools via MCP (Model Context Protocol) over HTTP. The MCP gateway is authenticated with SigV4:
python
class SigV4GatewayAuth(httpx.Auth):
    """Signs every MCP gateway request with SigV4 for AWS_IAM authorizers."""

    requires_request_body = True

    def auth_flow(self, request):
        credentials = self._session.get_credentials()
        frozen = credentials.get_frozen_credentials()
        body = request.content if request.content is not None else b""
        aws_request = AWSRequest(
            method=request.method,
            url=str(request.url),
            data=body,
            headers=dict(request.headers),
        )
        SigV4Auth(frozen, self._service, self._region).add_auth(aws_request)

        for key, value in aws_request.headers.items():
            request.headers[key] = value

        yield request
Each agent runs as a BedrockAgentCoreApp container. They're created with a Bedrock model, a system prompt, and the list of tools available to them:
python
def create_agent(tools, model_id=None) -> Agent:
    selected_model_id = model_id or os.environ.get("MODEL_ID", "anthropic.claude-haiku-4-5-20251001-v1:0")

    model = BedrockModel(model_id=selected_model_id)

    agent = Agent(
        model=model,
        system_prompt=COLLECTOR_AGENT_SYSTEM_PROMPT,
        name="Collector Agent",
        description="Collects and orchestrates reporting",
        tools=tools
    )
    return agent

@app.entrypoint
def invoke(payload, context=None):
    try:
        run_id = payload.get("run_id")
        start_date = payload.get("start_date")
        end_date = payload.get("end_date")

        # Build instruction with exact date authority
        instruction = (
            f"Use EXACT dates passed in payload for every tool call: "
            f"start_date={start_date}, end_date={end_date}."
        )

        with MCPClient(lambda: _create_gateway_transport(gateway_url)) as mcp_client:
            tools = _load_mcp_tools_sync(mcp_client)
            agent = create_agent(tools, model_id=model_id)

            # Run the agent with the instruction
            agent_output = agent.run(instruction)
The Collector and Reporter are separate containers with separate system prompts. The Collector's prompt tells it which tools exist and what parameters they require:
You are a data collection agent responsible for gathering AWS and Jira quarterly data using available gateway tools.

TOOL INPUT CONTRACTS:

1) p1_tickets
{
  "start_date": "ISO-8601",
  "end_date": "ISO-8601",
  "run_id": "<EXACT run_id value from your invocation payload>"
}

DATE AUTHORITY RULE (CRITICAL):
- NEVER invent dates
- NEVER modify dates
- ALWAYS pass the EXACT payload start_date and end_date to every tool call
- Use one identical date range across all tool calls
The Reporter's prompt emphasizes data sourcing and prevents hallucination by forcing tool calls to complete before writing:
Data retrieval rule:
- ALWAYS call the read_s3_buckets tool with the EXACT run_id from the payload before writing the report.
- First call read_s3_buckets with only run_id to fetch a manifest of available folders.
- Then call read_s3_buckets with run_id plus prefix and metadata_only=true to list object keys for each needed folder.
- For large folders, read full content key-by-key.
- Never claim "no data" for a section until key-level reads for that section are completed.
- If the S3 read returns no data, report that data is unavailable for this run_id.

Jira filters (strict):
- P1: include only tickets where priority == "Highest"
- Major updates: include only tickets where priority in {"High", "Medium"}
- A ticket classified as P1 must never be duplicated in Major updates
Data Handoff: How the Collector Stores Data
The Collector writes JSON to S3 after each tool call. Here's what the CloudWatch tool writes:
python
s3_payload = {
    "account_id": account_id,
    "status": "success",
    "metric_names": ["example1", "example2"],
    "namespace": "examples",
    "period_seconds": 43200,  # 12h
    "time_series": [
        {
            "metric_name": "example",
            "timestamp": "2026-06-30T12:00:00+00:00",
            "average_ms": 245.5
        },
        # ... more datapoints
    ],
    "data_points_count": 180,
    "generated_at": "2026-07-20T15:30:00+00:00"
}

s3.put_object(
    Bucket=bucket,
    Key=f"quarterly/{run_id}/cloudwatch/{account_id}.json",
    Body=json.dumps(s3_payload),
    ContentType="application/json"
)
The key structure is always quarterly/{run_id}/{tool_name}/{account_id}.json. Every tool follows this pattern, making it predictable for the Reporter to read.
What Gets Reported
The final HTML report has sections for:
- Availability and response time — CloudWatch metrics aggregated over the quarter
- P1 incidents — Highest-priority Jira tickets opened and resolved in the period
- Major updates — High and Medium priority Jira tickets
- Security patches — Applied across managed EC2 instances
- AWS outages — Events affecting the region during the quarter
- Backup activity — Restore jobs and backup completion status
What We Learned
The biggest challenge wasn't the agents themselves — it was making sure the Reporter couldn't hallucinate. LLMs will fill gaps with plausible-sounding data if you let them. The solution was structural: the Reporter only generates prose after doing key-level reads for every section, and the system prompt explicitly forbids claiming "no data" before completing those reads. The second thing was timeouts. Agent calls can take 10–20 minutes when they're reading dozens of S3 keys and generating a long HTML document. The Bedrock client needs a 20-minute read timeout, or the connection drops mid-report.
The architecture is straightforward: two agents, S3 as the handoff point, one Step Functions execution per quarter. The interesting part is the system prompts and the tool contracts. Get those right, and the agents handle the rest.